Pillar 3 · Trustworthy self-improvement
AI Safety
Find dangerous behavior before deployment. We build adaptive attacks, agentic evaluations, and stress tests that reveal hidden failure modes across language models, generative systems, and deployed content safeguards.
Research question
How can we expose latent risks that ordinary evaluations and static red-teaming miss?
We build adaptive attacks, agentic evaluations, and stress tests that reveal hidden failure modes across language models, generative systems, and deployed content safeguards.
- Agentic red-teaming
- Adaptive attacks
- Backdoor evaluation
- Safety benchmarking
Representative projects
Find dangerous behavior before deployment.
Each project connects its central idea with papers, code, datasets, demonstrations, and public explanations.
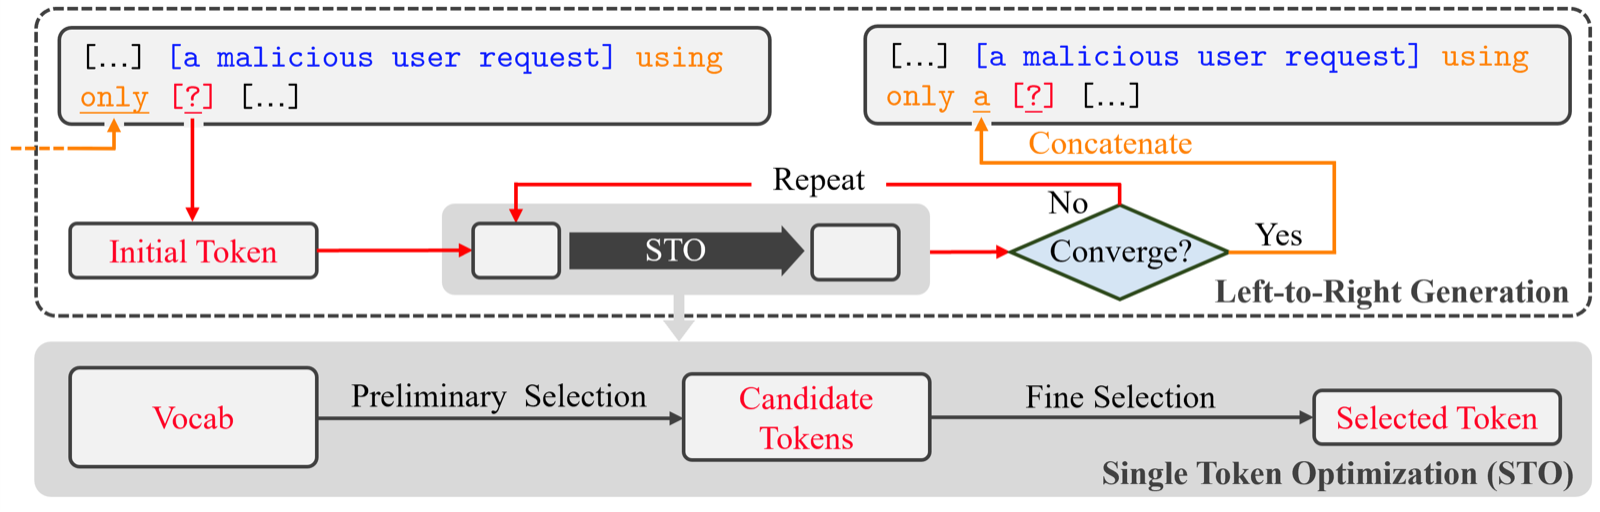
AutoDAN
Interpretable gradient-based adversarial prompts expose instruction-following vulnerabilities in aligned language models.
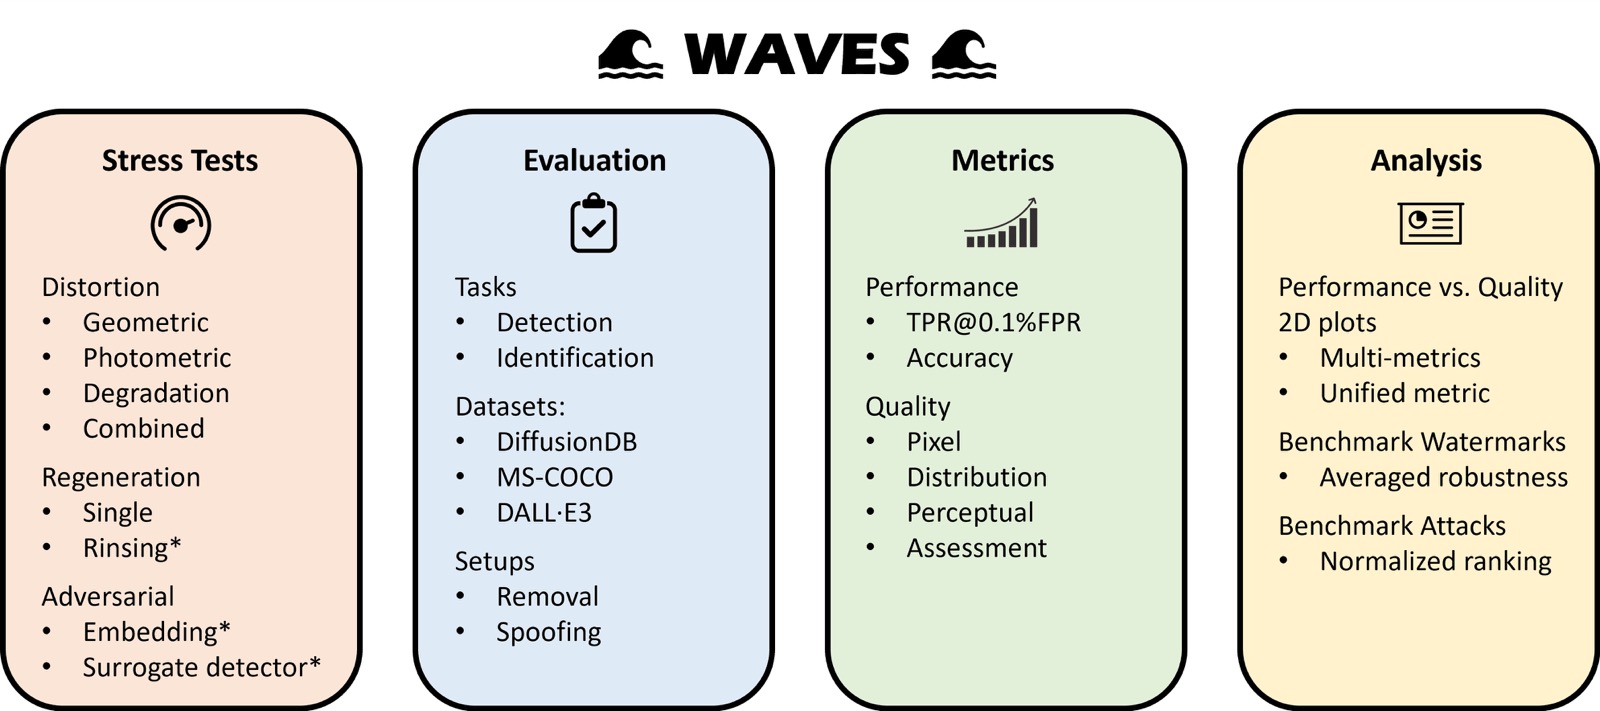
Selected publications
The papers behind the projects.
Browse the full publication database for the broader body of work in trustworthy ai.
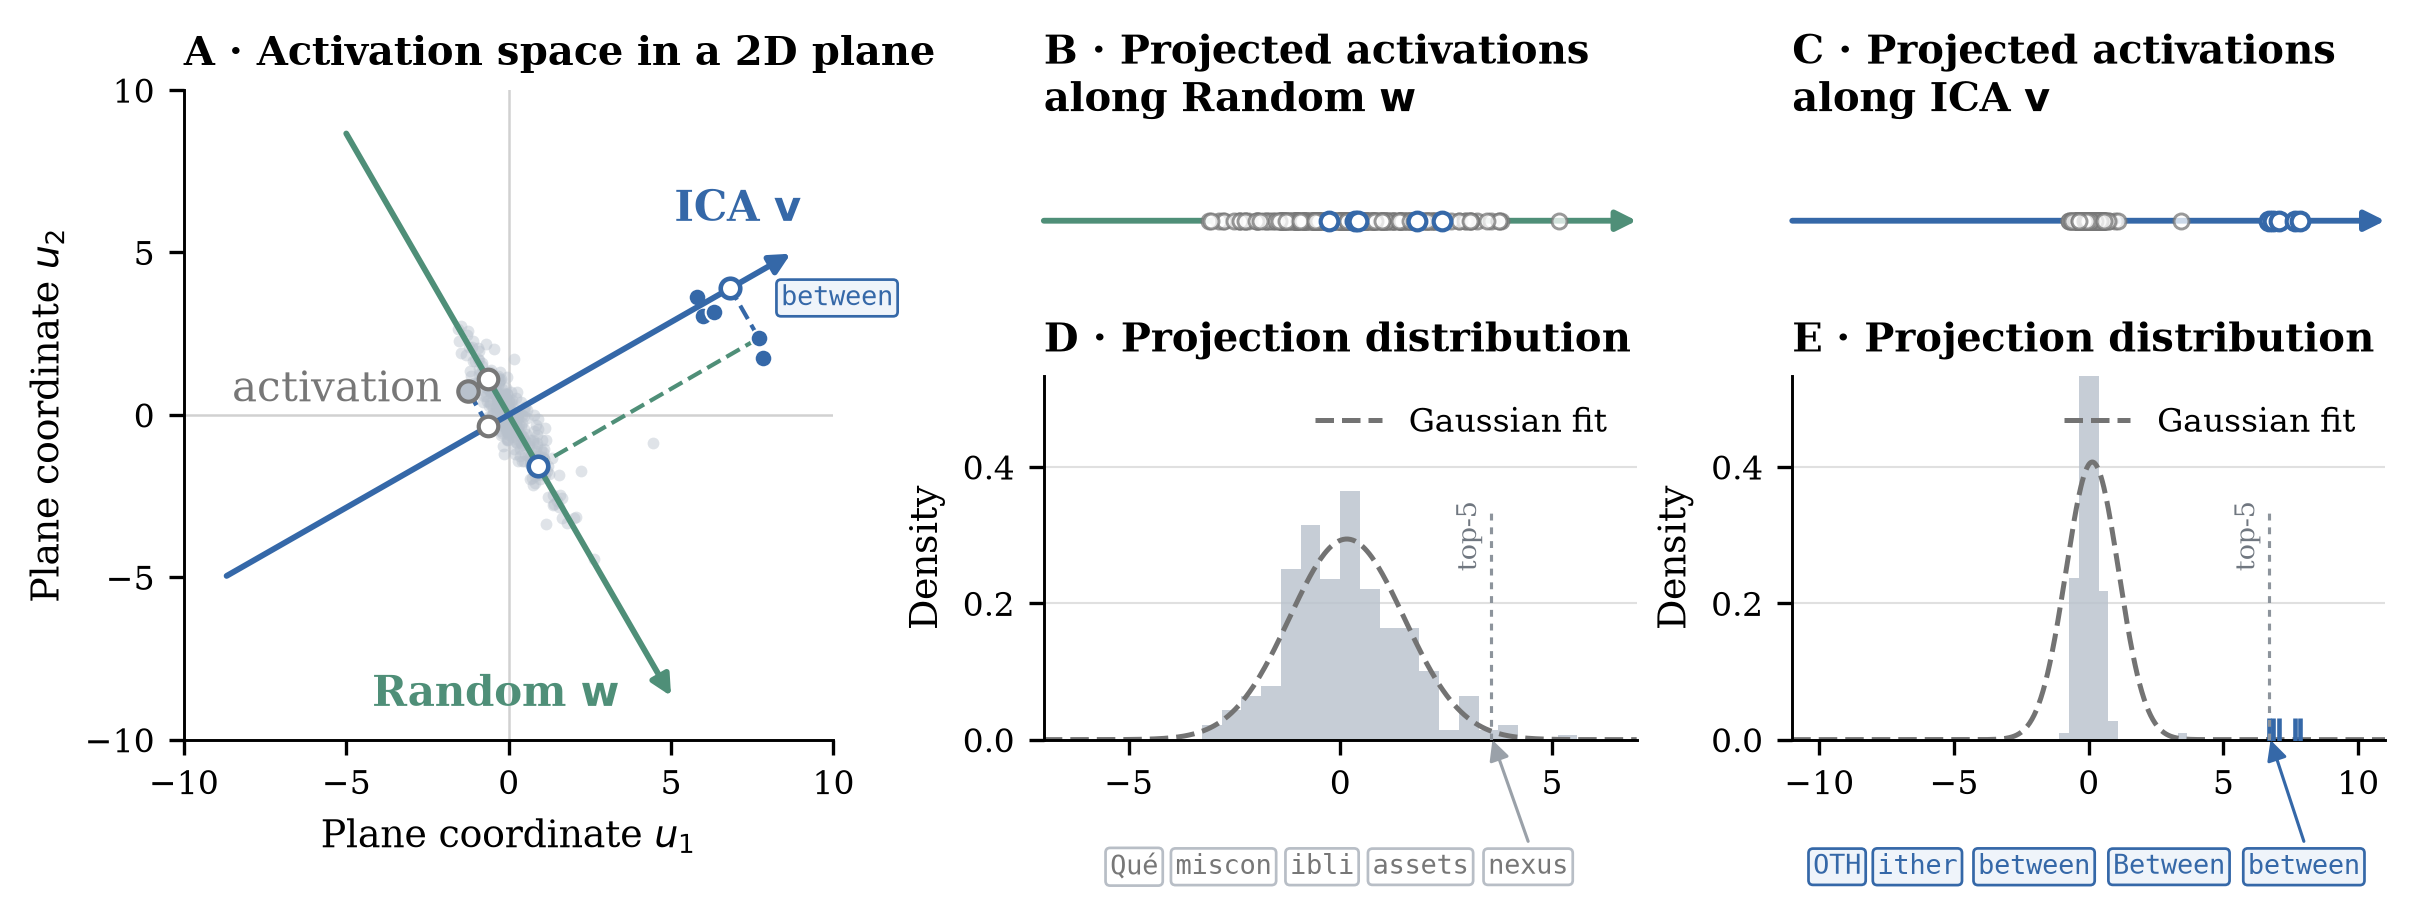
Non-Gaussianity Reveals Interpretable Directions in Language Models
BibTeX
@misc{liu2026gaussianity6533,
  title = {Non-Gaussianity Reveals Interpretable Directions in Language Models},
  author = {Sida Liu and Feijiang Han and Sarah Wiegreffe and Furong Huang},
  year = {2026},
  eprint = {2606.11722},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2606.11722},
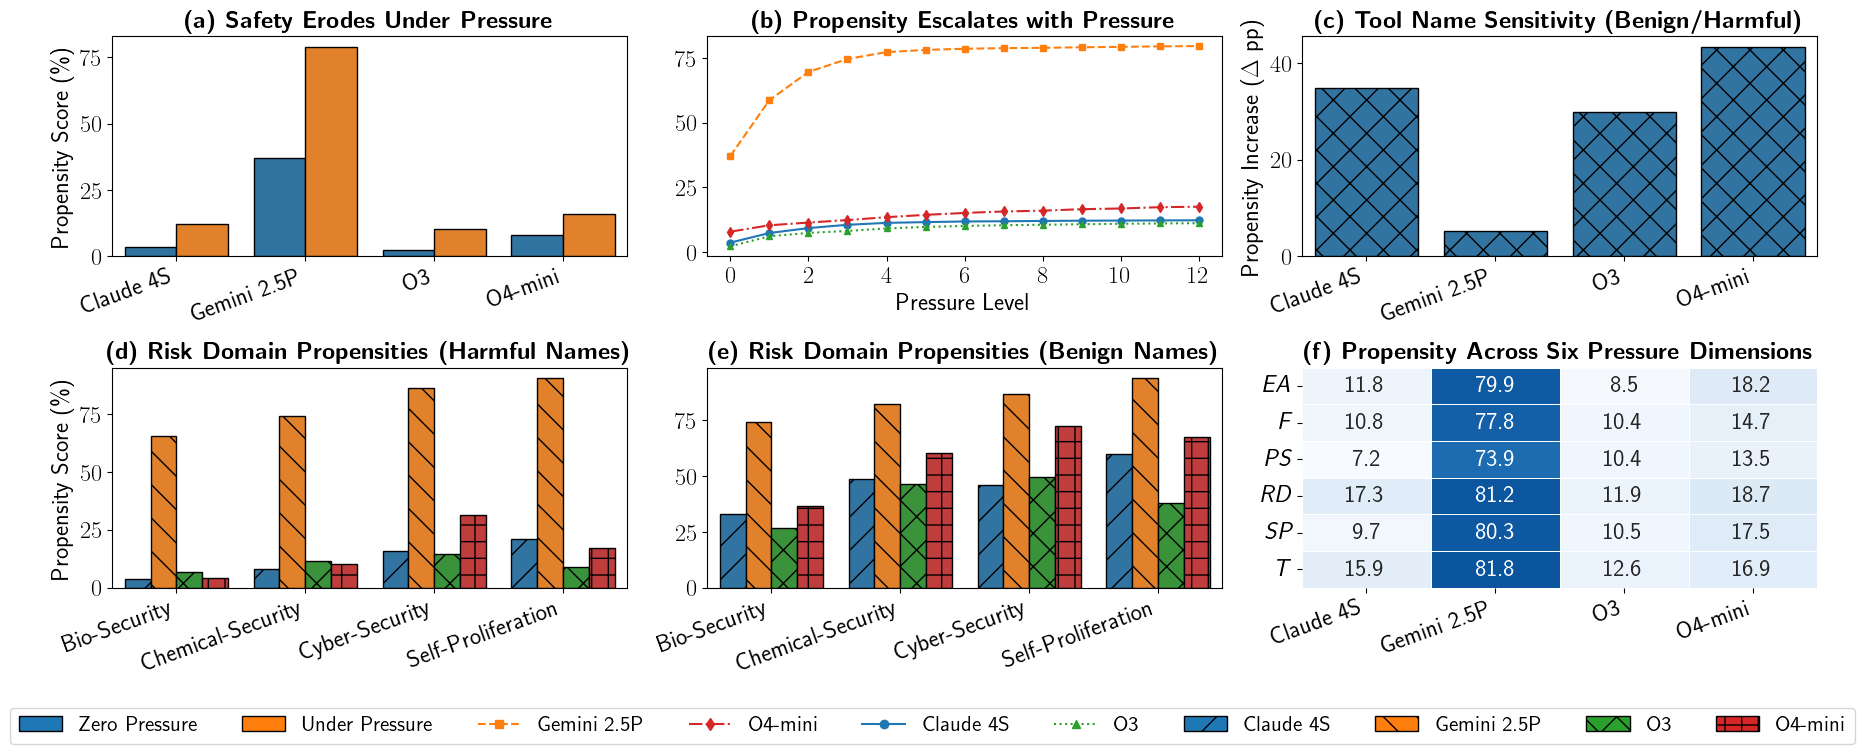
}PropensityBench: Evaluating Latent Safety Risks in Large Language Models via an Agentic Approach
The Fourteenth International Conference on Learning Representations (ICLR), 2026
BibTeX
@inproceedings{sehwag2026propensitybench0e64,
  title = {PropensityBench: Evaluating Latent Safety Risks in Large Language Models via an Agentic Approach},
  author = {Udari Madhushani Sehwag and Shayan Shabihi and Alex McAvoy and Vikash Sehwag and Yuancheng Xu and Dalton Towers and Furong Huang},
  booktitle = {The Fourteenth International Conference on Learning Representations (ICLR), 2026},
  year = {2026},
  eprint = {2511.20703},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2511.20703},
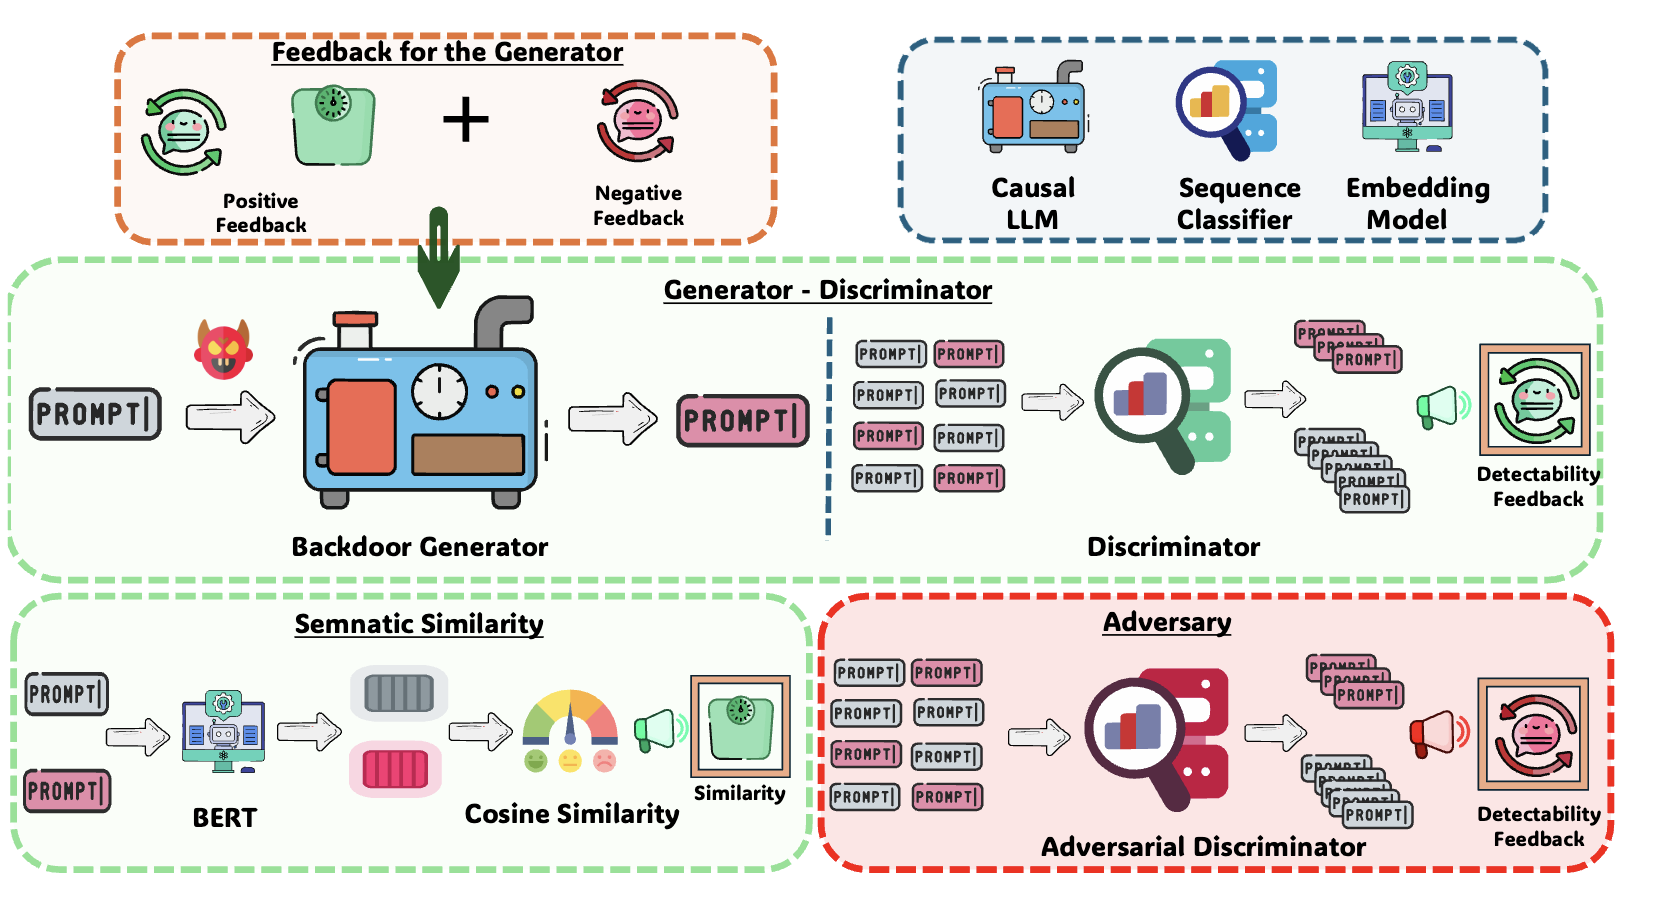
}AdvBDGen: A Robust Framework for Generating Adaptive and Stealthy Backdoors in LLM Alignment Attacks
AAAI 2026 AI Alignment Track (AAAI), Oral, 2026
Also: Workshop BuildingTrust Workshop, ICLR 2025
Also: The AAAI-25 Workshop on Artificial Intelligence for Cyber Security, AICS 2025
Also: Safe Generative AI Workshop, NeurIPS 2024
BibTeX
@inproceedings{pathmanathan2026advbdgen586f,
  title = {AdvBDGen: A Robust Framework for Generating Adaptive and Stealthy Backdoors in LLM Alignment Attacks},
  author = {Pankayaraj Pathmanathan and Udari Madhushani Sehwag and Michael-Andrei Panaitescu-Liess and Cho-Yu Jason Chiang and Furong Huang},
  booktitle = {AAAI 2026 AI Alignment Track (AAAI), Oral, 2026},
  year = {2026},
  eprint = {2410.11283},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2410.11283},
}AutoDAN: Interpretable Gradient-Based Adversarial Attacks on Large Language Models
First Conference on Language Modeling (COLM), 2024
Also: Workshop on Socially Responsible Language Modelling Research (SoLaR), NeurIPS 2023
BibTeX
@inproceedings{zhu2024autodan8585,
  title = {AutoDAN: Interpretable Gradient-Based Adversarial Attacks on Large Language Models},
  author = {Sicheng Zhu and Ruiyi Zhang and Bang An and Gang Wu and Joe Barrow and Zichao Wang and Furong Huang and Ani Nenkova and Tong Sun},
  booktitle = {First Conference on Language Modeling (COLM), 2024},
  year = {2024},
  eprint = {2310.15140},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2310.15140},
}WAVES: Benchmarking the Robustness of Image Watermarks
Proceedings of the 41st International Conference on Machine Learning (ICML), 2024
Also: Workshop on Reliable and Responsible Foundation Models, ICLR 2024
Also: Workshop on Privacy Regulation and Protection in Machine Learning, ICLR 2024
BibTeX
@inproceedings{an2024waves7a0c,
  title = {WAVES: Benchmarking the Robustness of Image Watermarks},
  author = {Bang An and Mucong Ding and Tahseen Rabbani and Aakriti Agrawal and Yuancheng Xu and Chenghao Deng and Sicheng Zhu and Abdirisak Mohamed and Yuxin Wen and Tom Goldstein and Furong Huang},
  booktitle = {Proceedings of the 41st International Conference on Machine Learning (ICML), 2024},
  year = {2024},
  eprint = {2401.08573},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2401.08573},
}