Fly-by-Code
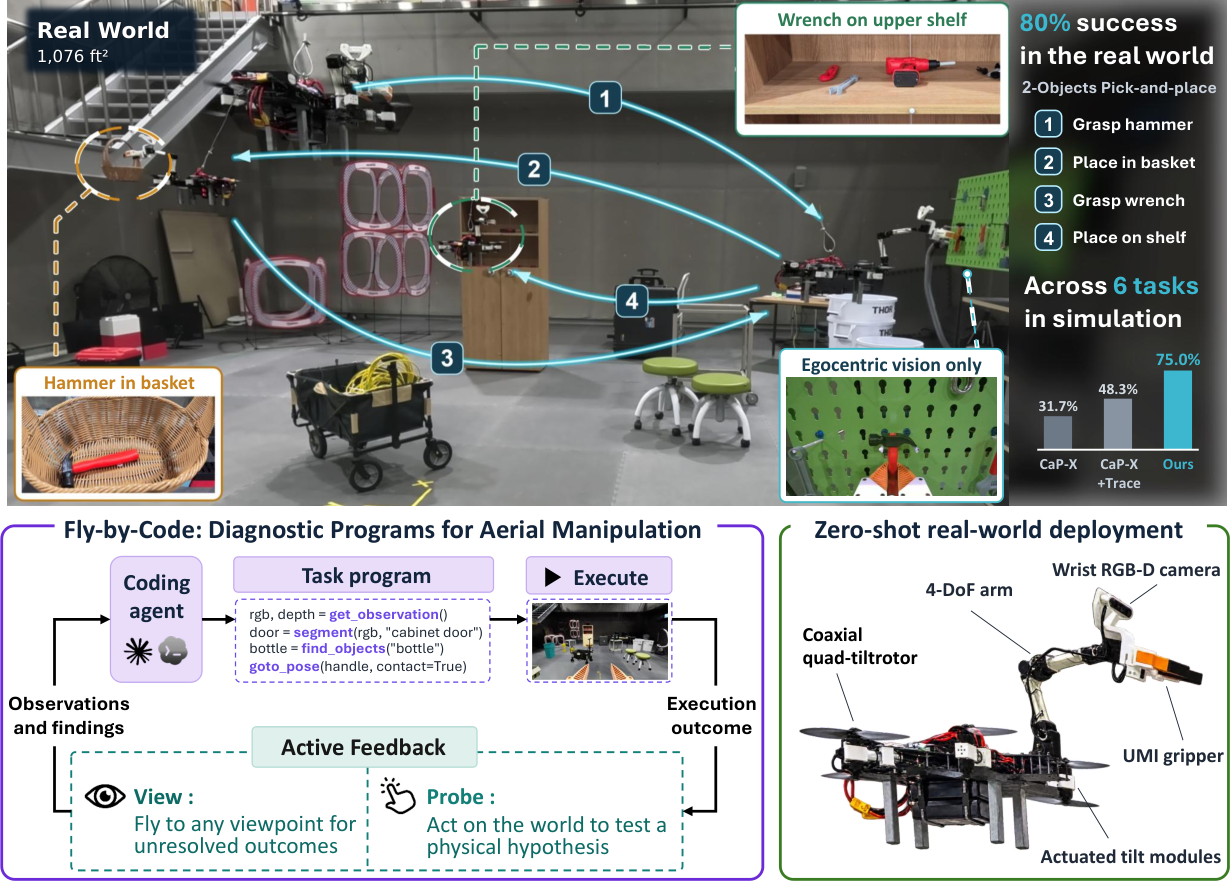
Embodied coding agents refine aerial-manipulation programs through active visual inspection and targeted physical diagnostic probes in simulation, then execute the programs on a real flying robot.
We build agents that learn the structure of interaction—not only pixels or text—so knowledge can transfer across tasks, scenes, cameras, and bodies.
Research question
Our approach combines reusable physical representations, explicit state, multimodal reasoning, and active verification. The goal is not merely to generate plausible futures, but to support reliable decisions in the real world.
Representative projects
Each project connects its central idea with the paper, code, demonstrations, and public explanations.
Embodied coding agents refine aerial-manipulation programs through active visual inspection and targeted physical diagnostic probes in simulation, then execute the programs on a real flying robot.
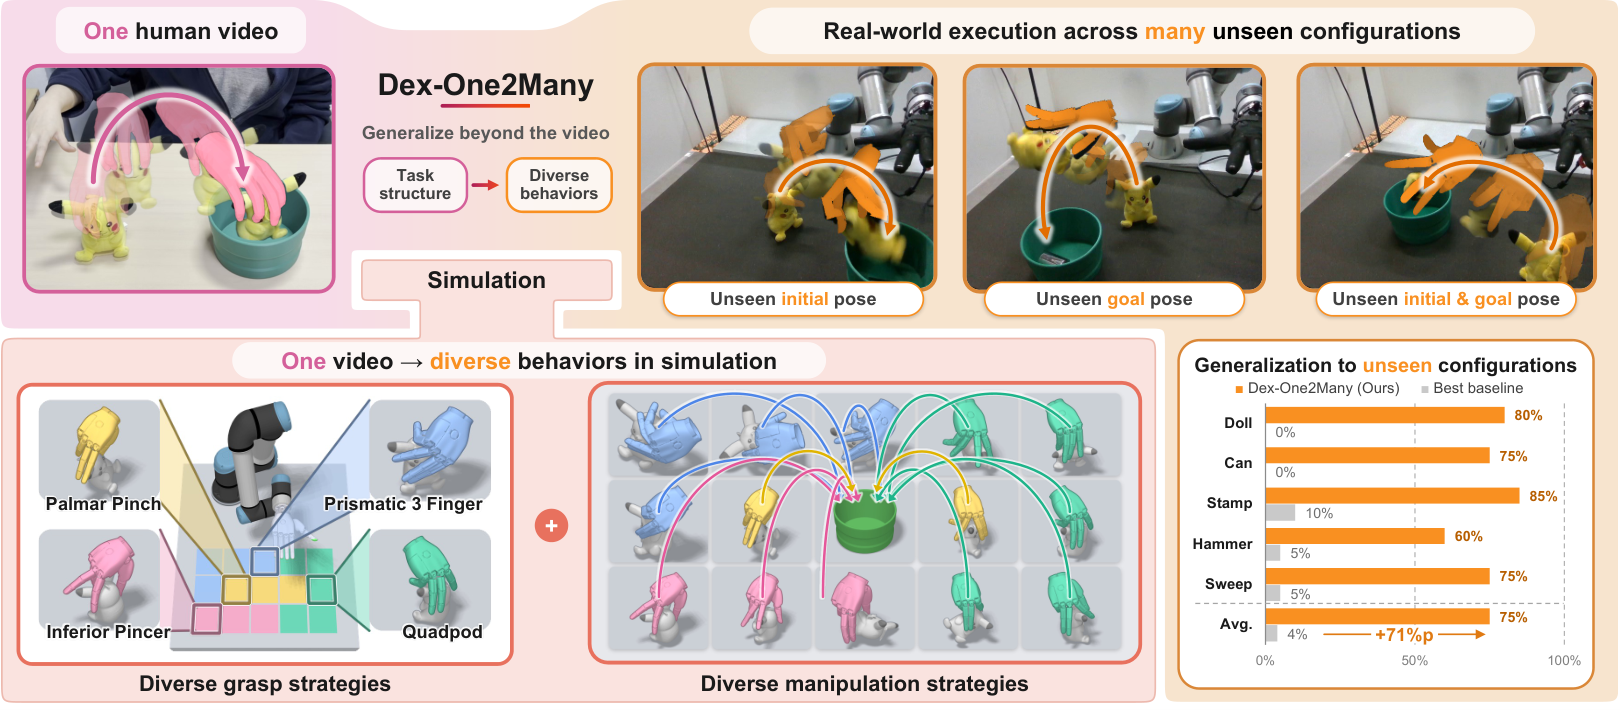
Learns dexterous manipulation from one human video by extracting stage-wise scene graphs that constrain diverse simulation training states and guide reinforcement learning, enabling zero-shot transfer to a real robot hand.
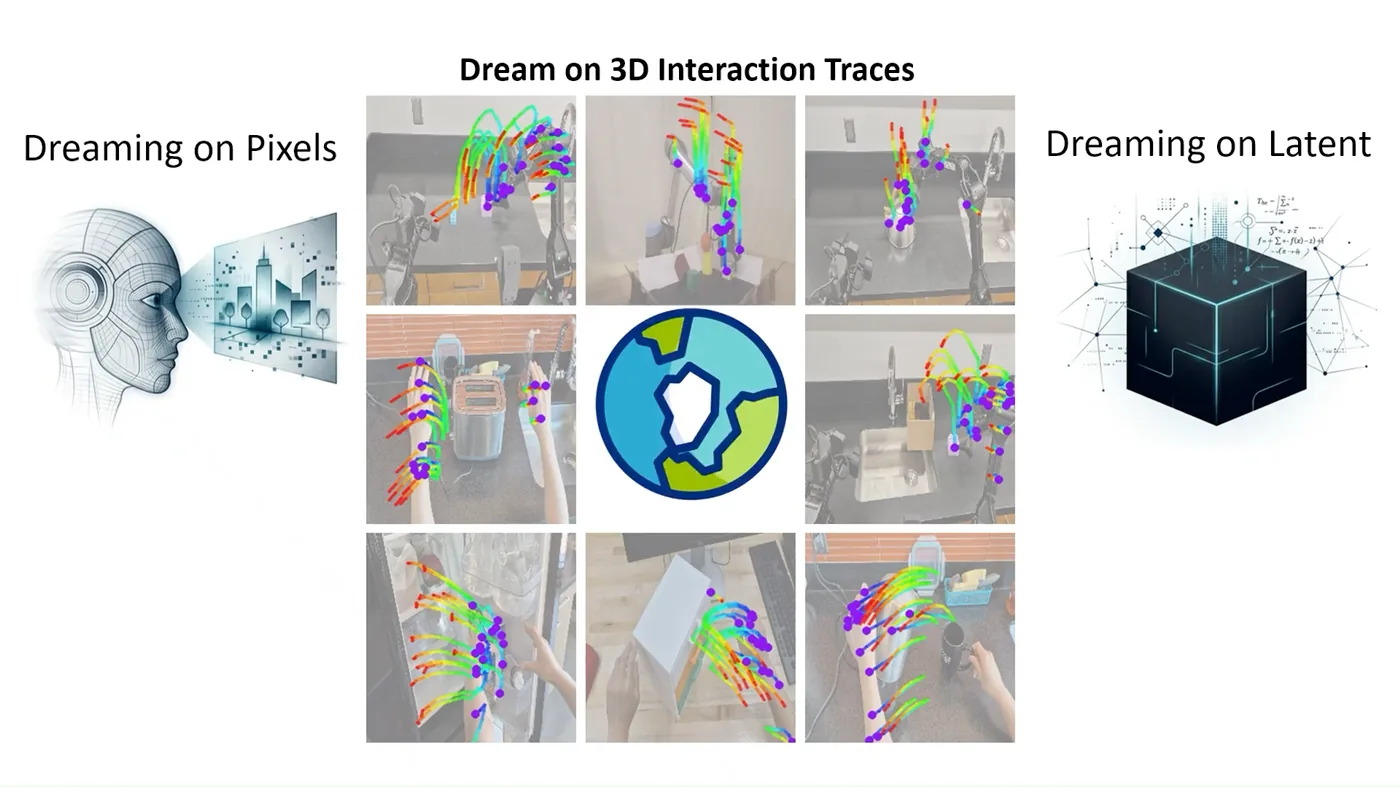
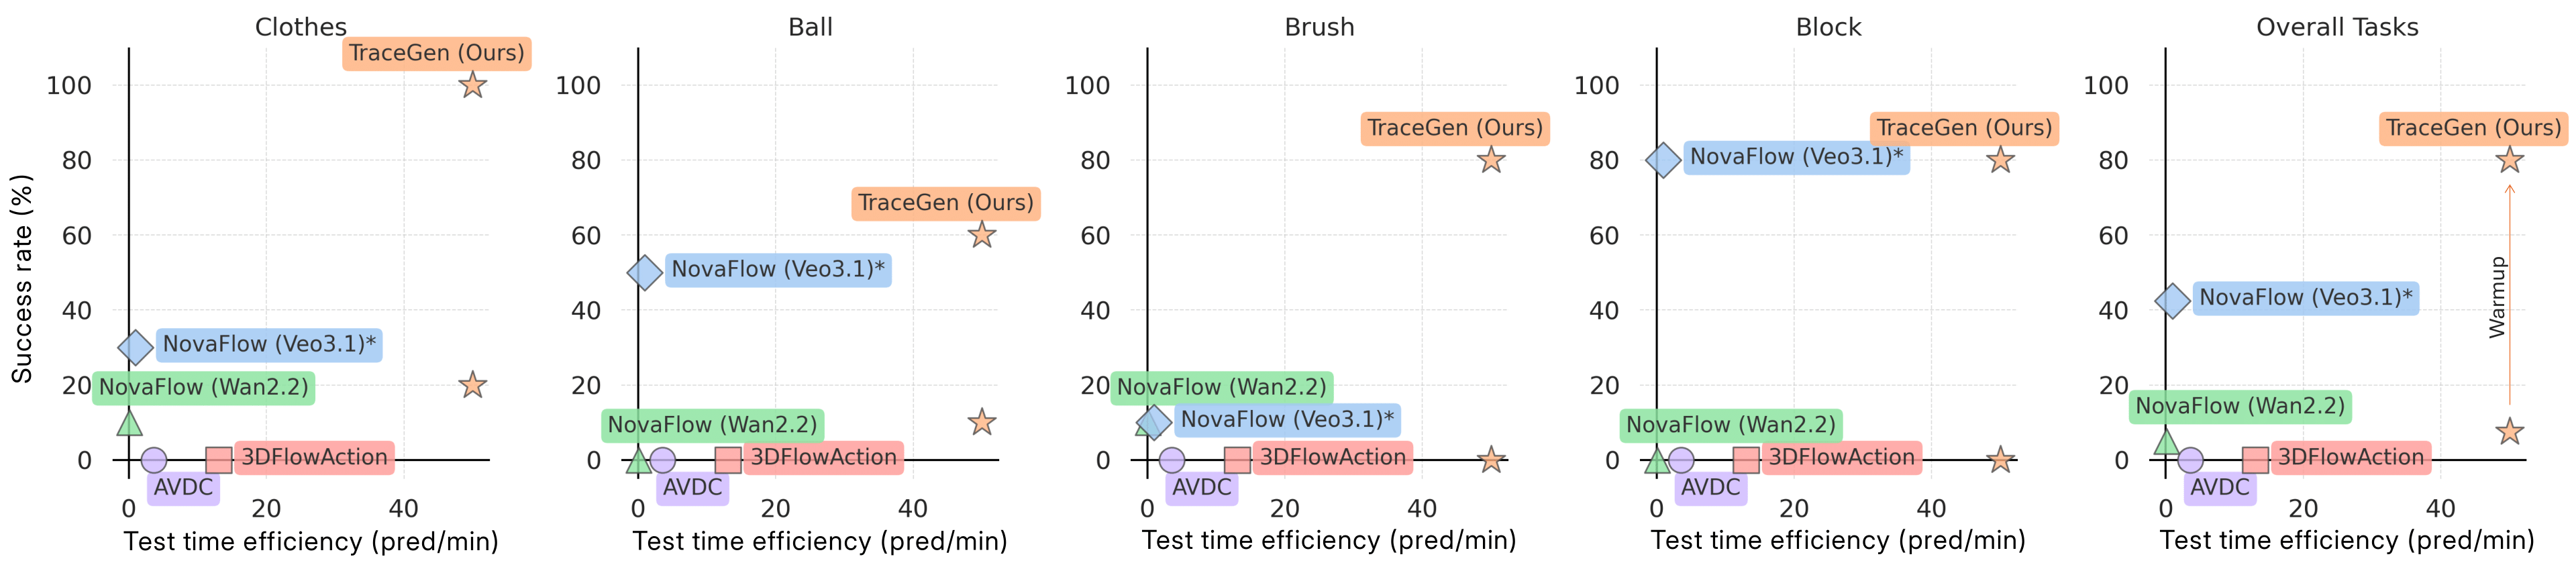
A scalable world model that predicts semantic 3D interaction traces, learning embodiment-agnostic motion priors from video-only pretraining for downstream robot control.
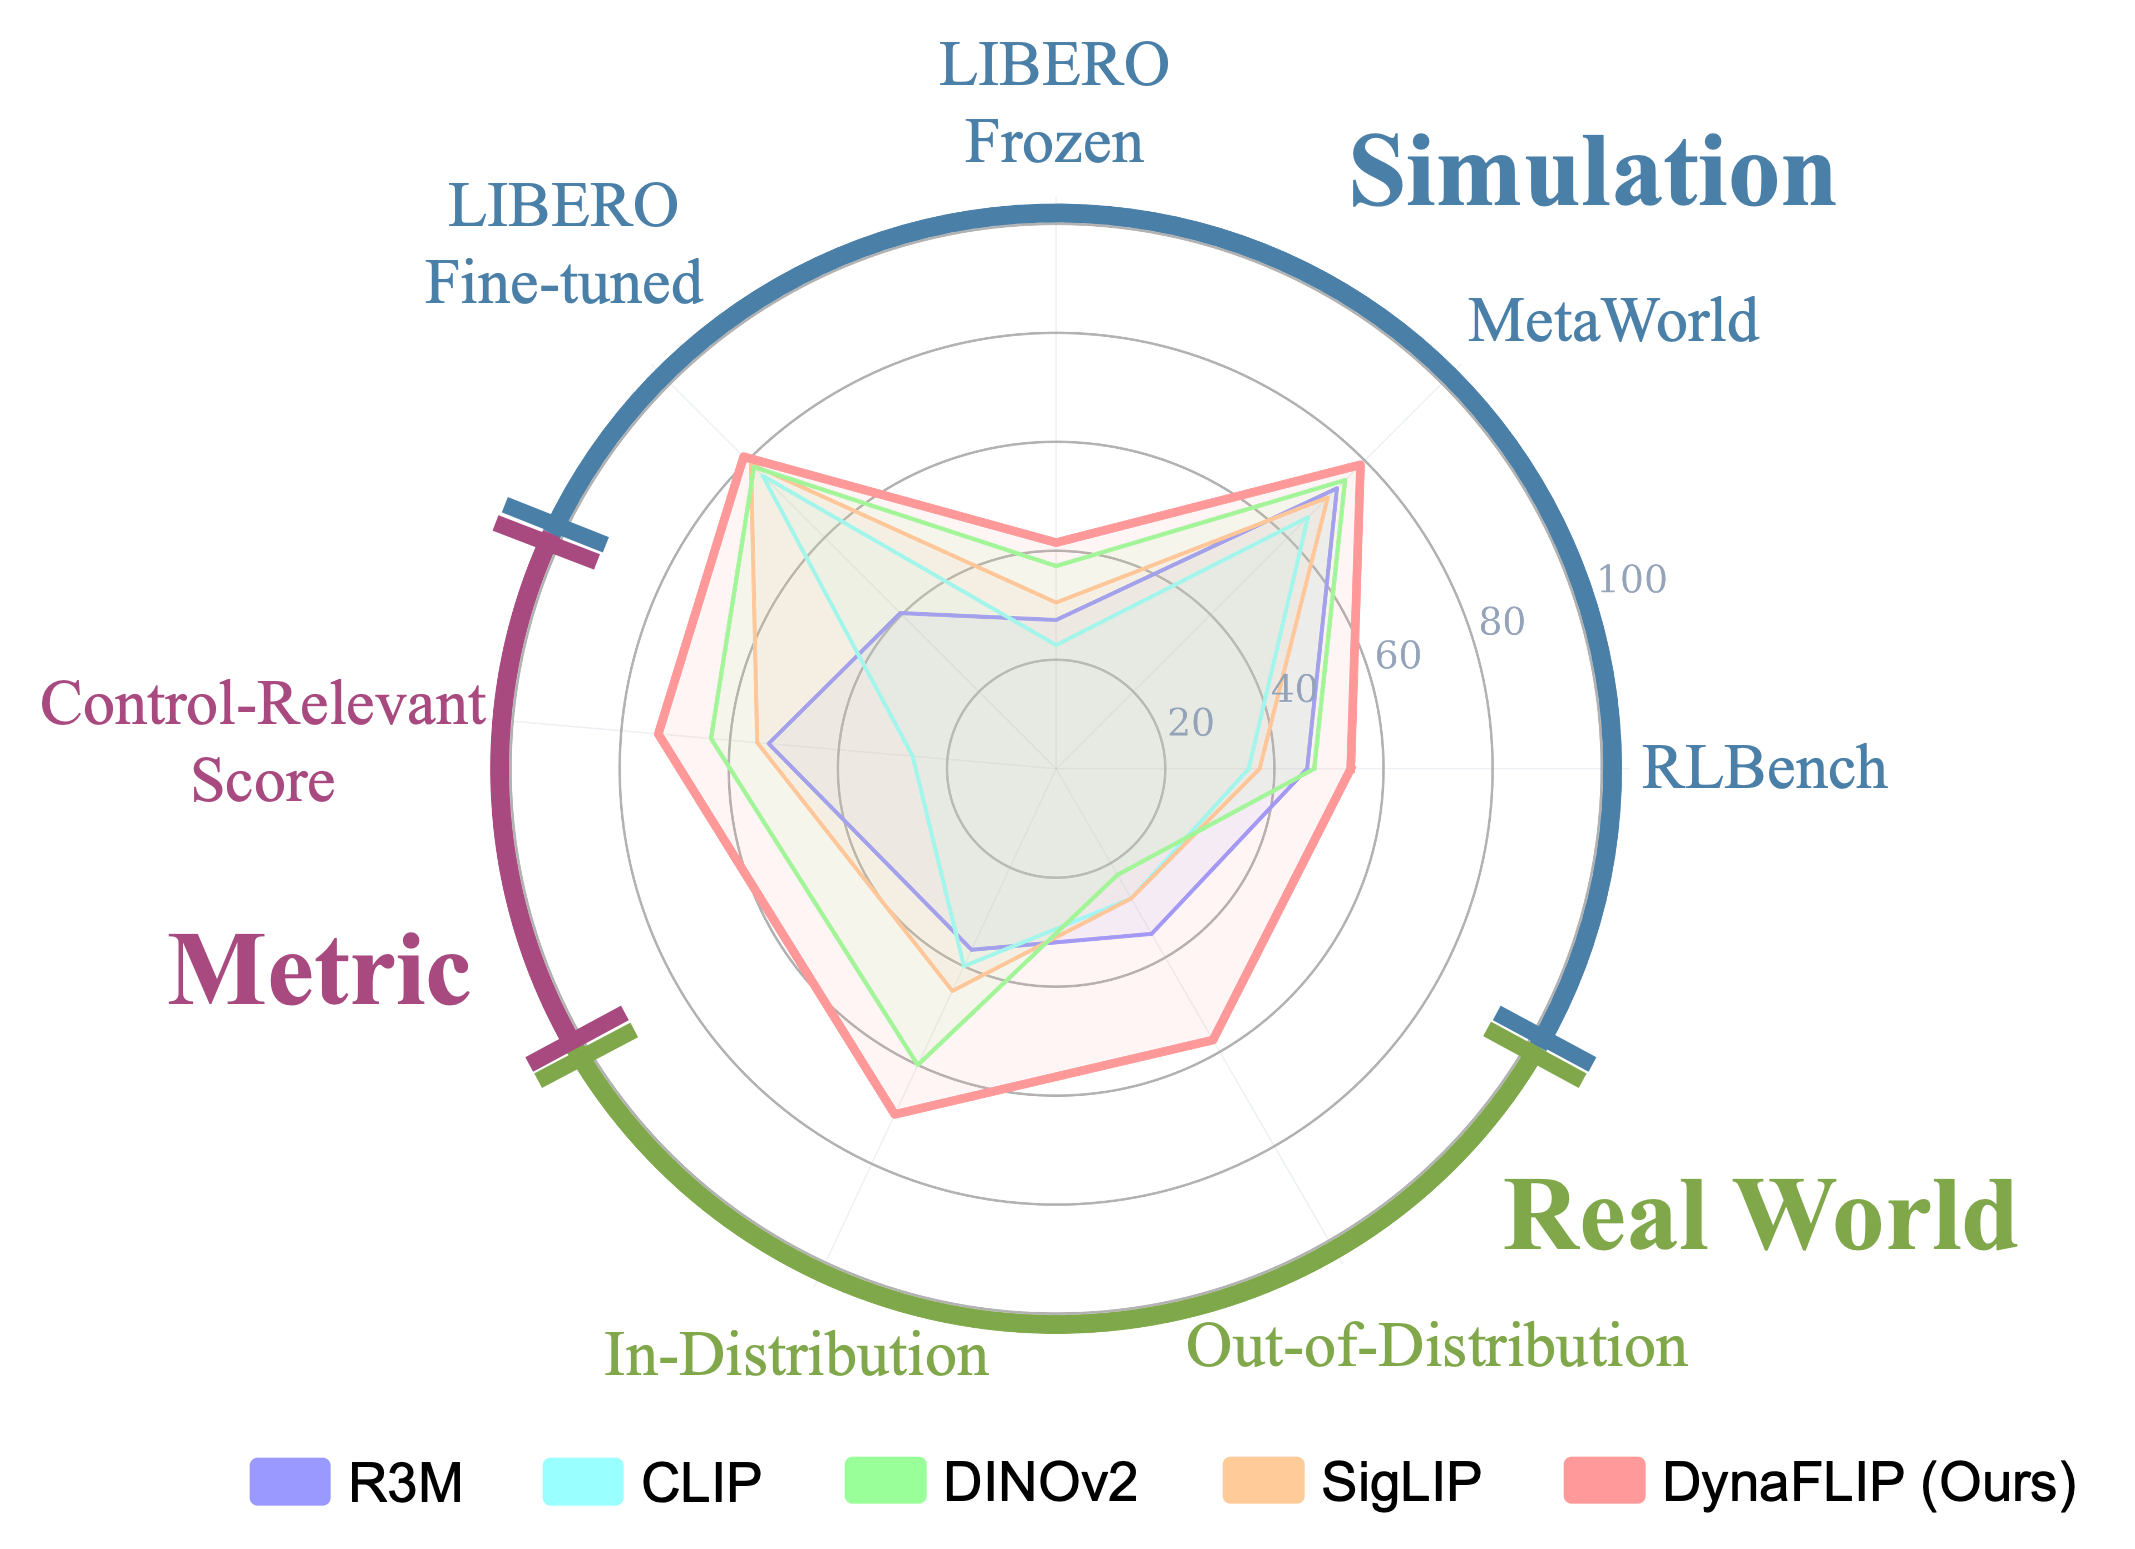
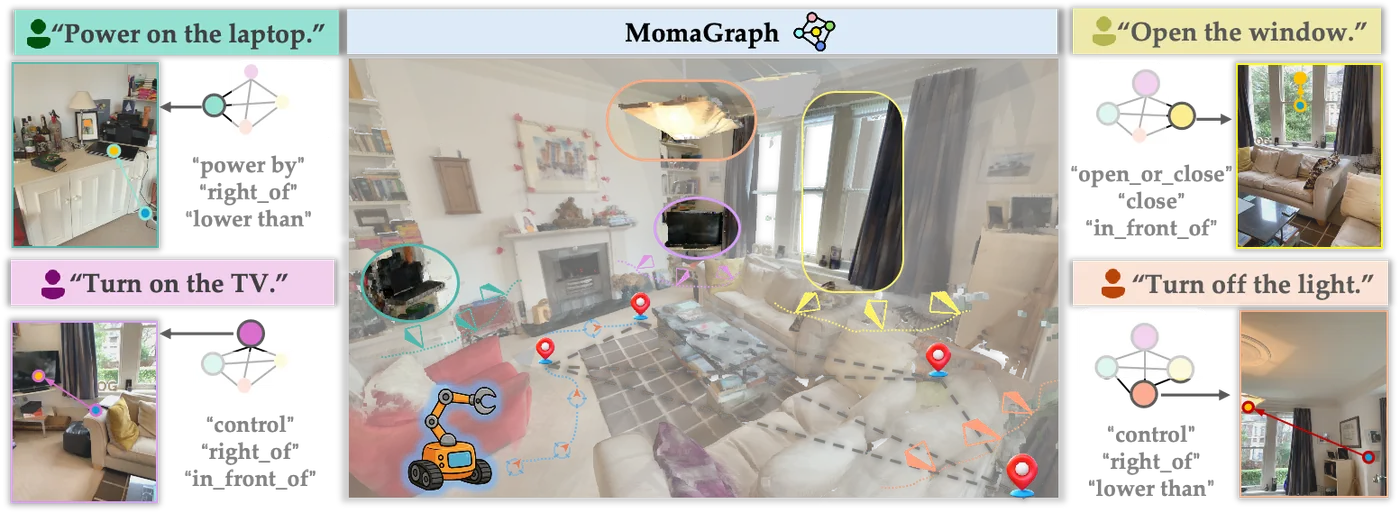
A dynamics-aware visual backbone for robot manipulation that aligns image transitions, language, and 3D flow to preserve control-relevant information.
Selected publications
The publications database presents the broader body of work on world models and embodied intelligence.
Conference on Robot Learning (CoRL), 2026
Also: RoBoWoMo Workshop, poster and spotlight, IROS 2026. Second-place Best Paper Award
@inproceedings{lee2026scalablef557,
  title = {μ0: A Scalable 3D Interaction-Trace World Model},
  author = {Seungjae Lee and Yoonkyo Jung and Jusuk Lee and Jonghun Shin and Amir Hossein Shahidzadeh and Yao-Chih Lee and H. Jin Kim and Jia-Bin Huang and Furong Huang},
  booktitle = {Conference on Robot Learning (CoRL), 2026},
  year = {2026},
  eprint = {2606.13769},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2606.13769},
}Conference on Computer Vision and Pattern Recognition (CVPR), 2026
@inproceedings{lee2026tracegen970c,
  title = {TraceGen: World Modeling in 3D Trace Space Enables Learning from Cross-Embodiment Videos},
  author = {Seungjae Lee and Yoonkyo Jung and Inkook Chun and Yao-Chih Lee and Zikui Cai and Hongjia Huang and Aayush Talreja and Tan Dat Dao and Yongyuan Liang and Jia-Bin Huang and Furong Huang},
  booktitle = {Conference on Computer Vision and Pattern Recognition (CVPR), 2026},
  year = {2026},
  eprint = {2511.21690},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2511.21690},
}Conference on Neural Information Processing Systems (NeurIPS), Main Track, Poster, 2026
Also: Robotics World Modeling Workshop, NeurIPS 2026
@inproceedings{lee2026dynaflip336f,
  title = {DynaFLIP: Rethinking Robotics Perception via Tri-Modal-Dynamics Guided Representation},
  author = {Jusuk Lee and Seungjae Lee and Jonghun Shin and Hoseong Jung and Sungha Kim and Daesol Cho and H. Jin Kim and Jia-Bin Huang and Furong Huang},
  booktitle = {Conference on Neural Information Processing Systems (NeurIPS), Main Track, Poster, 2026},
  year = {2026},
  eprint = {2605.30350},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2605.30350},
}The Fourteenth International Conference on Learning Representations (ICLR), Oral, 2026
@inproceedings{ju2026momagraphf0b4,
  title = {MomaGraph: State-Aware Unified Scene Graphs with Vision-Language Model for Embodied Task Planning},
  author = {Yuanchen Ju and Yongyuan Liang and Yen-Jen Wang and Nandiraju Gireesh and Yuanliang Ju and Seungjae Lee and Qiao Gu and Elvis Hsieh and Furong Huang and Koushil Sreenath},
  booktitle = {The Fourteenth International Conference on Learning Representations (ICLR), Oral, 2026},
  year = {2026},
  eprint = {2512.16909},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2512.16909},
}9th Annual Conference on Robot Learning (CoRL), 2025
@inproceedings{lee2025imagineef14,
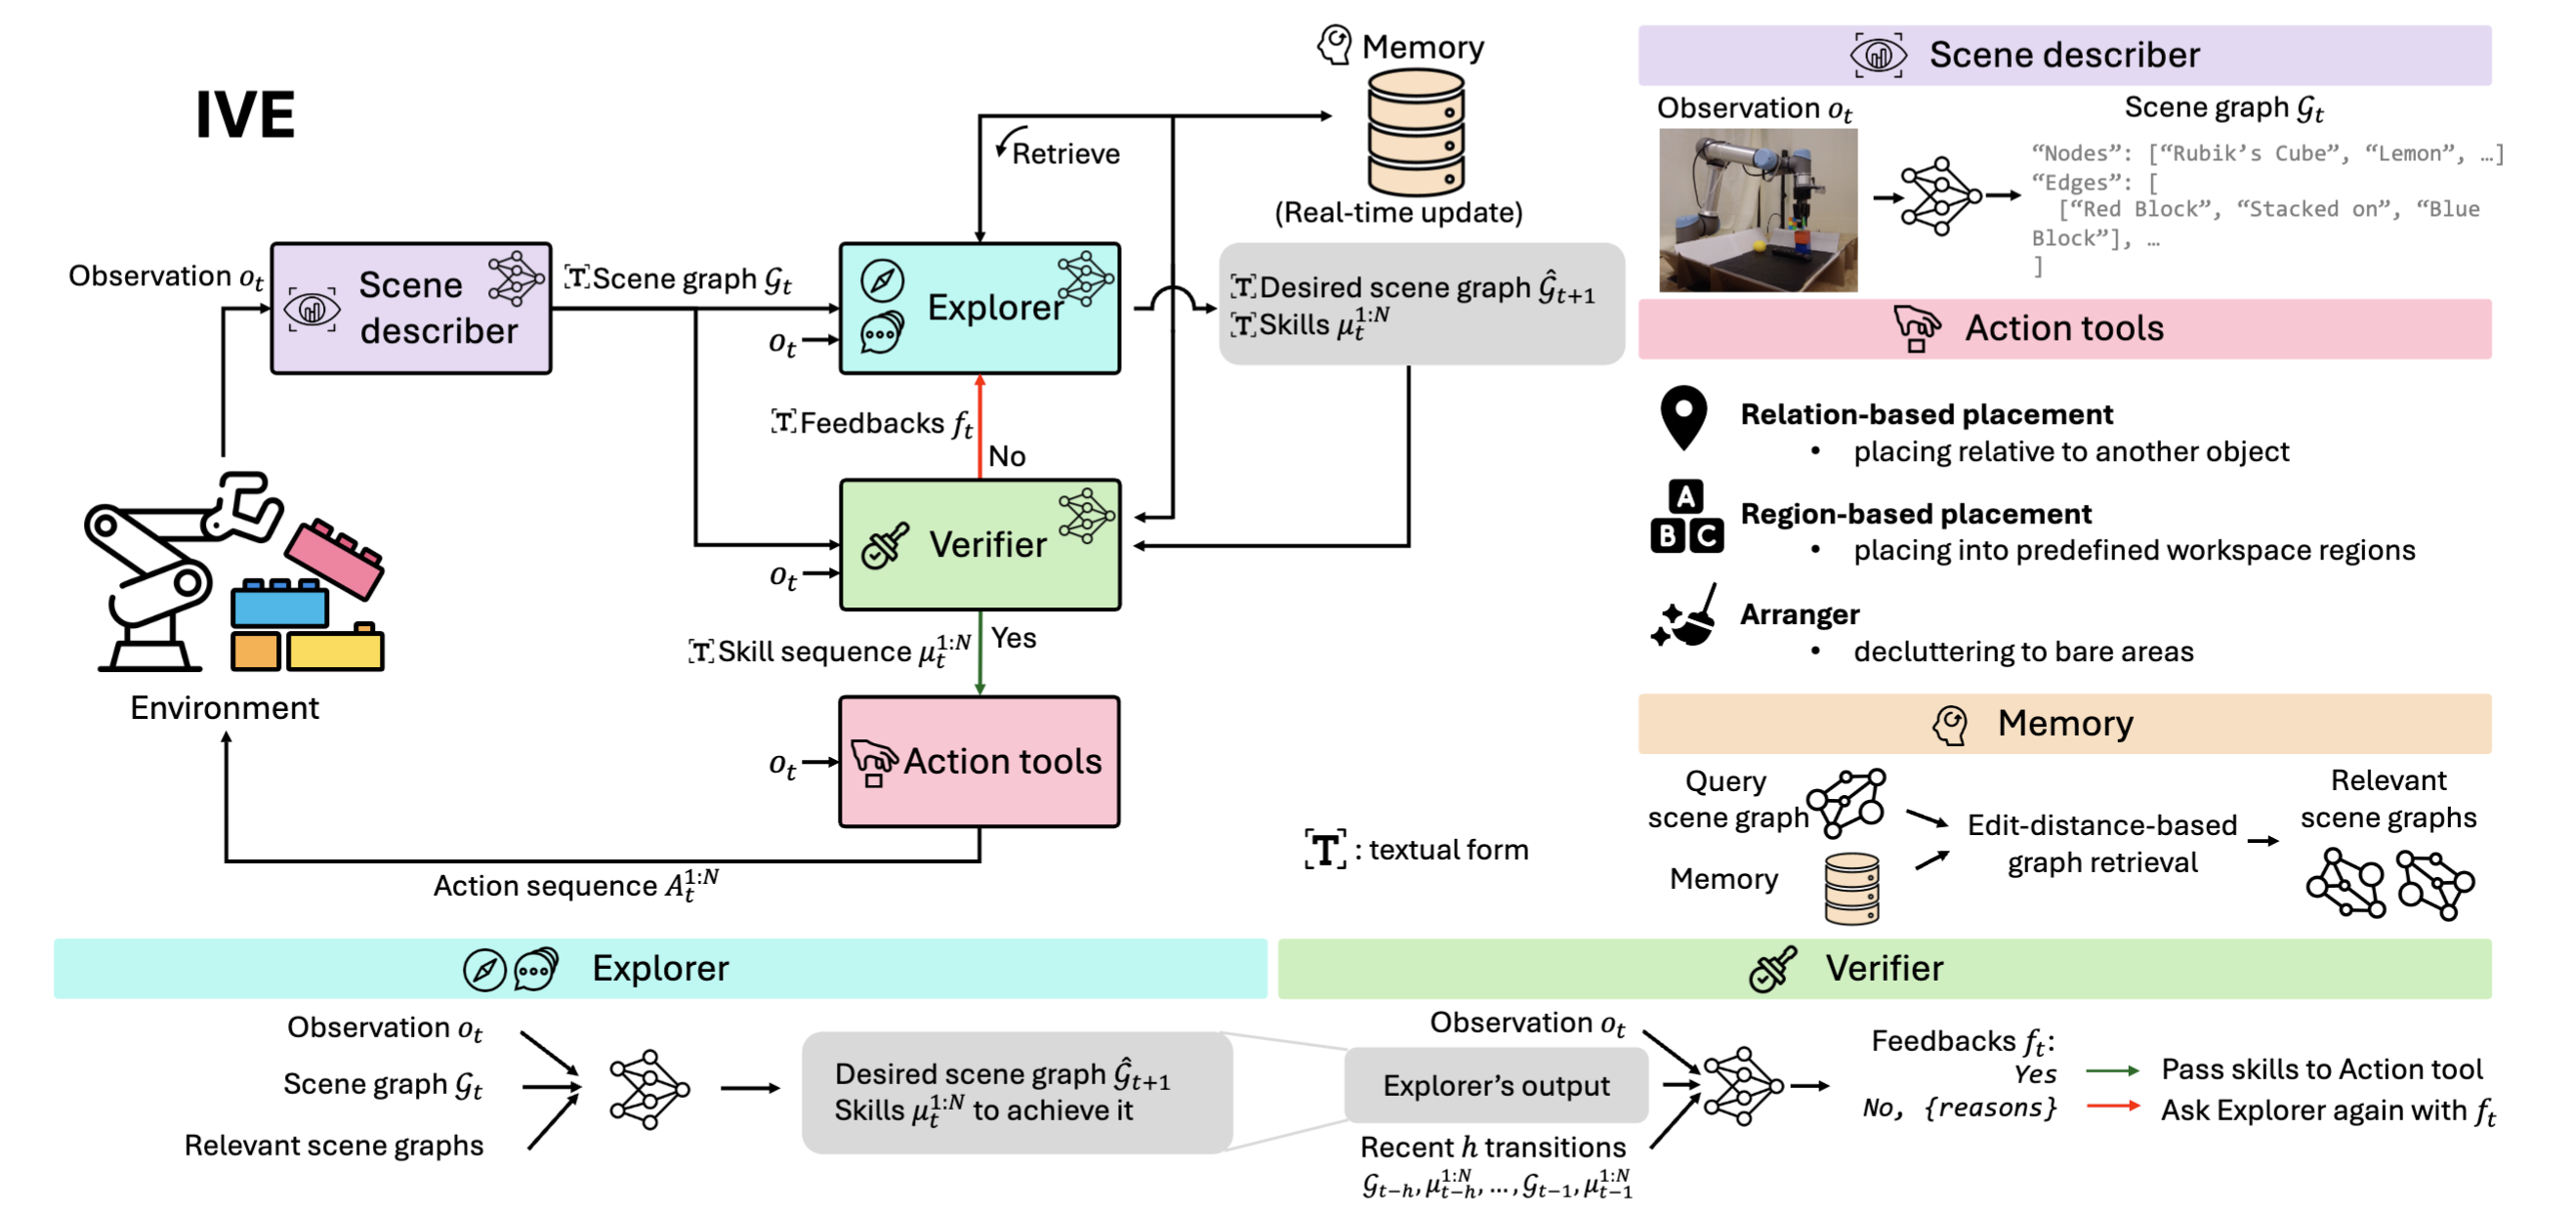
  title = {Imagine, Verify, Execute: Agentic Exploration with Vision-Language Models},
  author = {Seungjae^ Lee and Daniel Ekpo^ and Haowen Liu and Furong Huang and Abhinav Shrivastava and Jia-Bin Huang},
  booktitle = {9th Annual Conference on Robot Learning (CoRL), 2025},
  year = {2025},
  eprint = {2505.07815},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2505.07815},
}The Thirty-eighth Annual Conference on Neural Information Processing Systems (NeurIPS), 2024
Also: Adaptive Foundation Models: Evolving AI for Personalized and Efficient Learning, oral, NeurIPS 2024
@inproceedings{liang2024makee784,
  title = {Make-An-Agent: A Generalizable Policy Network Generator with Behavior-Prompted Diffusion},
  author = {Yongyuan Liang and Tingqiang Xu and Kaizhe Hu and Guangqi Jiang and Furong Huang and Huazhe Xu},
  booktitle = {The Thirty-eighth Annual Conference on Neural Information Processing Systems (NeurIPS), 2024},
  year = {2024},
  eprint = {2407.10973},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2407.10973},
}ScaleInfra Workshop, oral, IROS 2026
Also: Workshop on Data-Centric Robotics: What Data Do Robots Really Need, RSS 2026
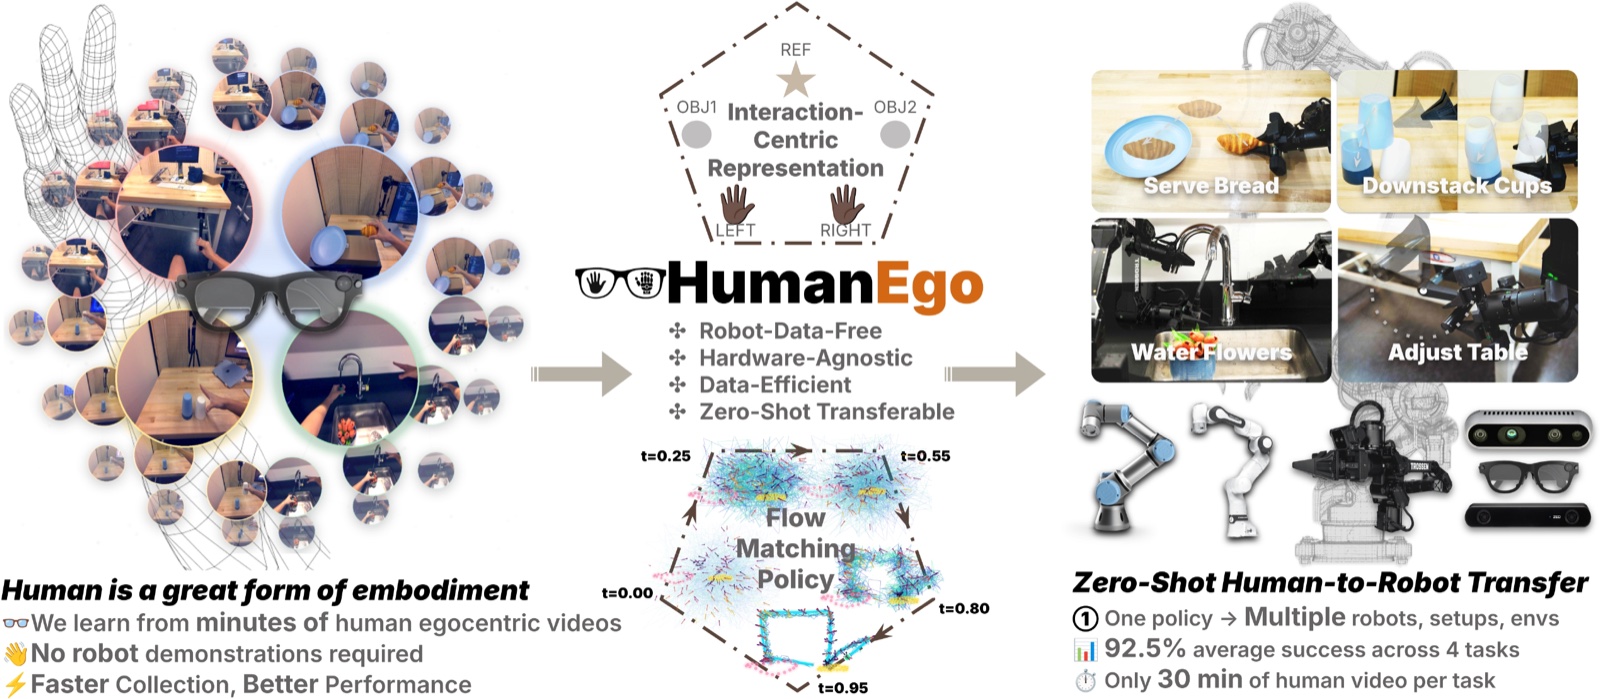
@inproceedings{wang2026humanegoa2a2,
  title = {HumanEgo: A Zero-Instrumentation Data-to-Deployment Pipeline for Robot Learning from Human Egocentric Video},
  author = {Zhi Wang and Botao He and Kelin Yu and Seungjae Lee and Ruohan Gao and Furong Huang and Yiannis Aloimonos},
  booktitle = {ScaleInfra Workshop, oral, IROS 2026},
  year = {2026},
  eprint = {2605.24934},
  archivePrefix = {arXiv},
  url = {https://openreview.net/forum?id=y8NCjfHKL7},
}